Quick Answer
Dubbing a 30-second clip on Percify costs 60 credits and takes about 3 minutes at 480p using the fast model. The same clip at 720p costs 180 credits and takes about 11 minutes. That is 3x the price for 3.9x the wait, and the difference is visible only when the face fills more than about a third of the frame. Measured across 179 production jobs, of which none failed.
Measured across 179 jobs: 480p fast runs 2 credits per second of audio, 720p costs three times that and takes almost four times longer.
Keep reading
Related next steps
We pulled every InfiniteTalk job our platform has run, 179 of them, and measured the real numbers rather than quoting a price list. Per second of source audio:
| credits per second | wait per audio second | a 30 second clip | |
|---|---|---|---|
| 480p fast | 2.00 | 5.7s | 60 credits, about 2m50s |
| 480p standard | 4.00 | 8.7s | 120 credits, about 4m20s |
| 720p standard | 6.00 | 22.3s | 180 credits, about 11m |
The row people misjudge is the last one. Moving to 720p costs three times the credits of fast 480p, which most people accept without thinking. It also costs 3.9 times the wall clock time, because 720p spends 22 seconds of compute for every second of audio. A two minute video at 720p is a 45 minute wait. Nobody tells you that before you click, and it is not visible on the pricing page either, because it is a compute characteristic rather than a price.
You can check the current credit values on the pricing page, but the ratios above are what matter when you are choosing settings.
Most dubbing is short, and that changes the right default
Of those 179 jobs, 118 were under 30 seconds. Another 41 were under a minute. Only nine ran longer than 75 seconds.
That distribution is the entire argument for making fast 480p your default. At the clip lengths people actually dub, the visible quality difference is small and the waiting difference is the whole experience. A 20 second product clip finishes in under two minutes on fast. The same clip at 720p takes seven.
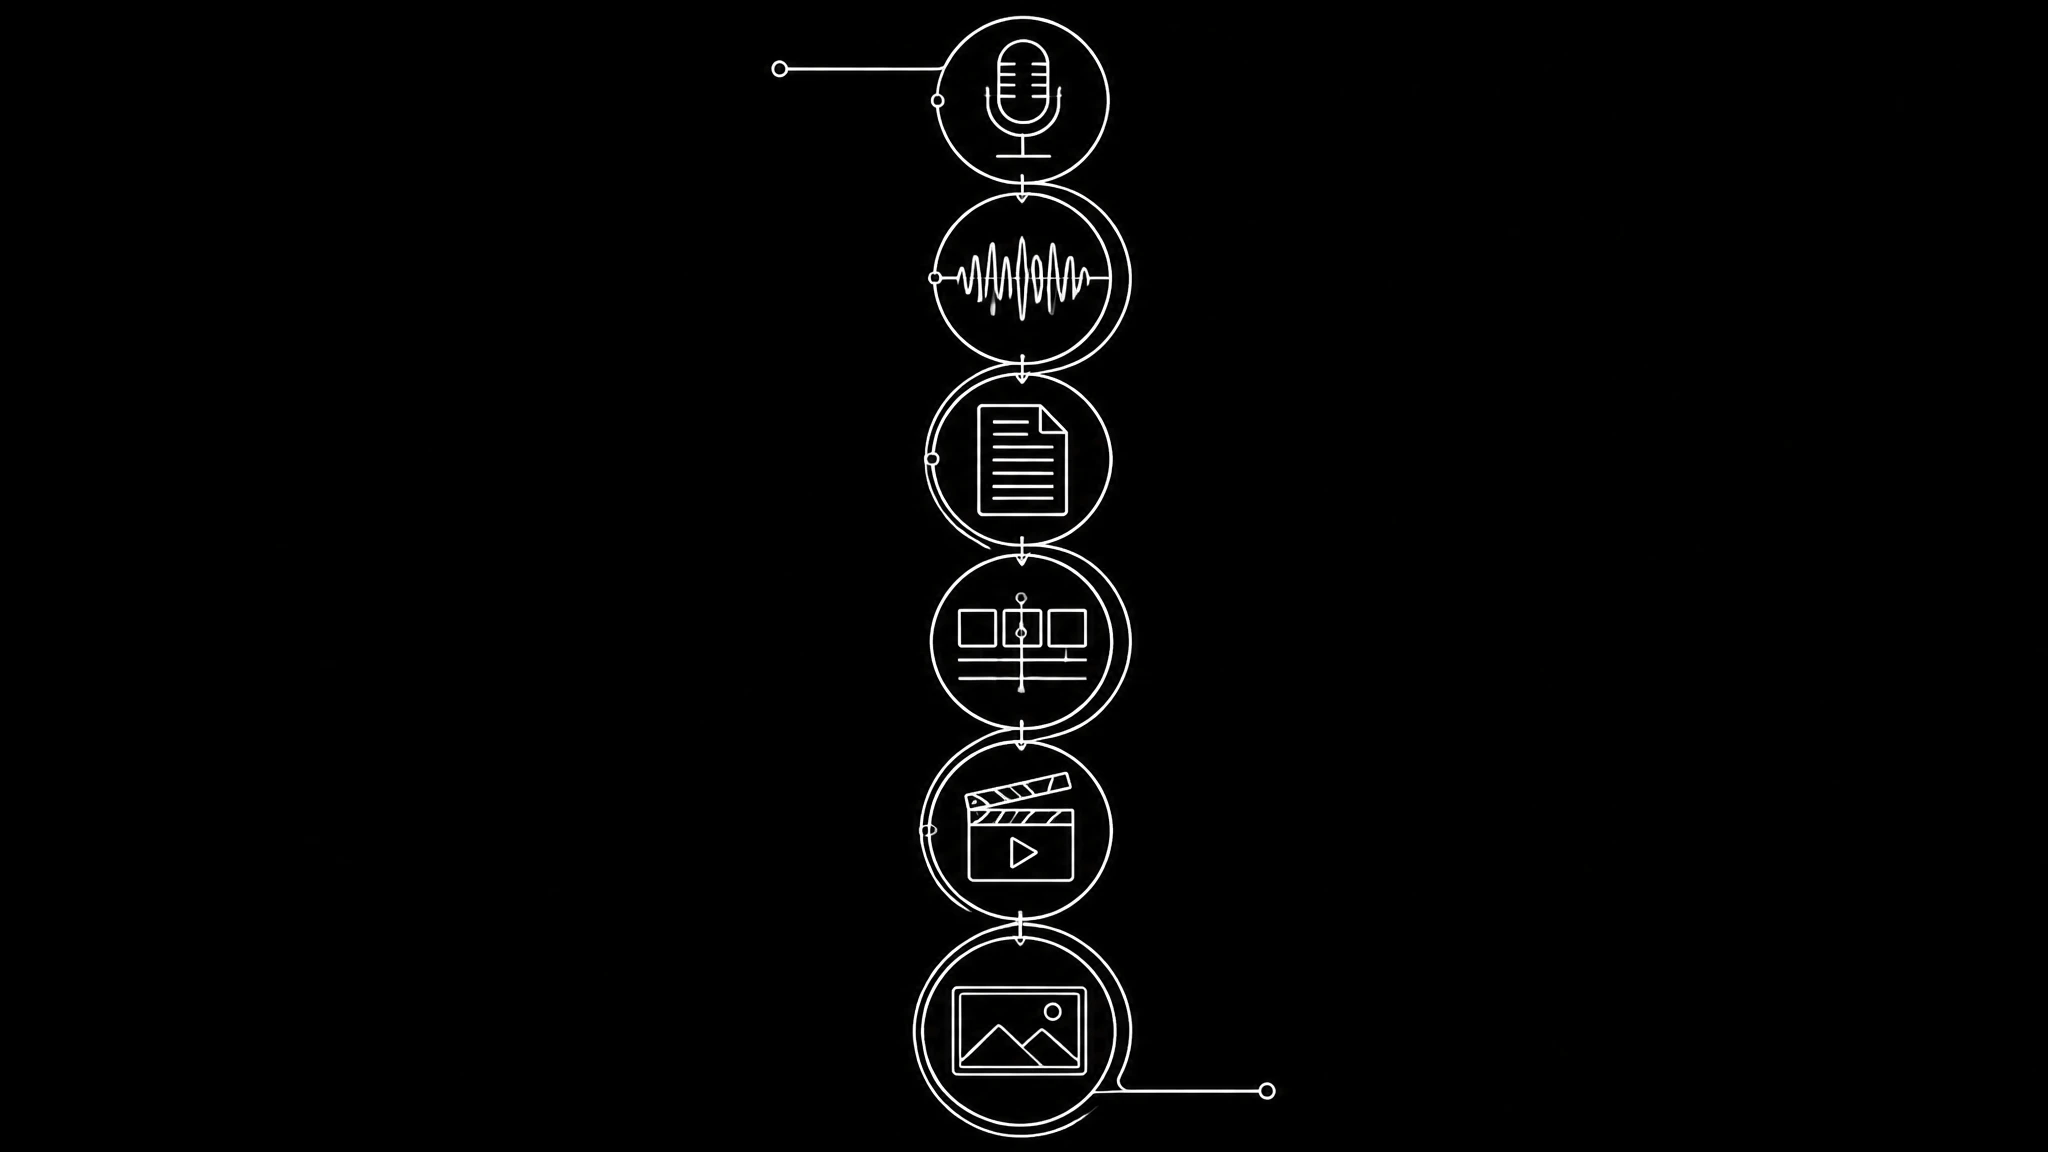
Step one, extract the script with timing
Run speech to text over the original audio, the same transcription step behind our captions tooling. The output you need is not just words, it is per segment start and end times. A transcript without timestamps will cost you sync later, because the next step changes how long every sentence takes to say.
How long each language actually runs
Translation changes duration, and that is what breaks sync. Rough expansion against English, which is what you plan around:
| target language | typical length change |
|---|---|
| German | 20 to 30 percent longer |
| French | 15 to 20 percent longer |
| Spanish | 15 to 25 percent longer |
| Portuguese | 15 to 25 percent longer |
| Italian | 10 to 20 percent longer |
| Japanese | 10 to 20 percent shorter |
| Korean | roughly level to slightly shorter |
| Mandarin | 10 to 25 percent shorter |
The practical consequence is asymmetric. Languages that run long force you to either speed the delivery or trim words, and both are noticeable if the segment was tight to begin with. Languages that run short leave gaps, which are easier to absorb because a pause reads as natural where a rushed line does not.
If you are localising one video into several languages at once, script for the longest one. The same principle applies to any avatar video you plan to reuse across markets. A sentence that fits German comfortably will fit Japanese with room to spare, and the reverse is not true.
Step two, translate without breaking the timing
A literal translation almost always changes duration. German runs roughly 20 to 30 percent longer than English. Japanese often runs shorter. A translation that ignores this hands you audio that no longer fits the picture.
Lock proper nouns before this step, exactly as you would when scripting an AI avatar video. Product names, people, and companies are the most common source of output that sounds obviously machine made. A sentence can be grammatically perfect and still be wrong because it pronounced your brand like a French verb.
Step three, clone the voice
This is the difference between dubbing and voiceover. A cloned voice keeps the original speaker's timbre in the new language, so the video still sounds like the person on screen. Voice cloning quality depends heavily on the sample, and the ElevenLabs guidance on recording clean input ↗ is a good primer whichever tool you use. Twenty to thirty seconds of clean speech is enough, and the same cloning that powers dubbing drives every avatar we generate. Background music in that sample noticeably degrades the result, so pick a quiet passage. Consent for a cloned voice is a separate question from consent for a face, and the copyright position is the part most people skip.
If you skip cloning you get a generic voice reading a translation over someone else's face, which viewers read as a dub immediately.
Step four, regenerate the mouth from the translated audio
Without this you have new audio over an unchanged mouth, the single most common complaint we see about AI dubbing tools. That is the effect everyone recognises as a bad dub. When the mouth comes back wrong, the four fault signatures tell you which stage to redo rather than rerunning the whole job.
The important detail is which audio drives the regeneration. Lip movement must be generated from the translated track, not the original. If your tool translates audio and leaves the video alone, the mouth will be forming shapes that belong to a language nobody is hearing. We go through the failure modes in more depth in why AI lip sync looks wrong.
A worked example, with real numbers
Take a 45 second product explainer, one speaker, seated, of the kind you might build in the avatar studio, face filling roughly a third of the frame. You want English, German and Spanish.
At 480p fast the arithmetic is direct. 45 seconds at 2.00 credits per second is 90 credits per language, so 180 credits for the two dubs. Wall clock at 5.7 seconds of compute per audio second is about 4 minutes 15 seconds each, and the jobs do not queue behind each other, so call it under ten minutes to have both.
At 720p the same job is 270 credits per language and roughly 16 minutes each. For a talking head at that framing, the extra detail lands almost entirely on parts of the frame nobody is looking at.
Now change one thing. Make it a wide shot where the speaker occupies a fifth of the frame. Now 720p is worth its cost, because the mouth region is small enough that the extra pixels are the difference between a rebuilt mouth and a smudge. The decision was never about the video's importance. It was about how many pixels the mouth occupies.
Where the money actually goes when you scale
The economics change shape once you pass about three languages. A single dub is cheap enough that nobody optimises it. Ten languages of a two minute video at 720p is 1,440 credits and around three hours of compute, which is worth checking against what each plan includes, and at that point the resolution decision is a real budget line rather than a preference. At volume the cost question becomes a plan question, and the current pricing is the only honest way to model it.
This is also where the review step stops being optional. Ten languages means ten passes of proper noun checking, and the cost of skipping it multiplies by the same factor as everything else.
Step five, read the output before anyone else does
Across our 179 jobs the technical failure rate was zero. Nothing errored. Every complaint we have seen is about output that succeeded and still was not usable, and almost all of it is caught by reading along once:
Numbers and dates read in the wrong convention, which the CLDR locale data ↗ exists to standardise and which most pipelines ignore. Acronyms spelled out in one language and pronounced as a word in another. Emphasis landing on the wrong word in a sentence that is otherwise correct. Brand names, again.
A 30 second clip has maybe five of these. Fixing them takes two minutes.
Step six, watch the last ten seconds
Sync error accumulates. If it exists, it shows at the end, not the beginning. Producing subtitles alongside the dub is worth the extra pass, and the W3C guidance on audio and video accessibility ↗ is the clearest summary of what good ones contain. Watch the closing seconds before publishing anything, and split any video longer than two minutes into parts.
Where 720p genuinely earns its cost
Lip sync models rebuild the mouth region, so what limits quality is how many pixels the mouth occupies, not the number on the resolution label. A head and shoulders shot at 480p gives the model more mouth detail than a wide shot at 720p.
So the rule is about framing. If the face is smaller than about a quarter of the frame width, 720p helps. If the face already fills the frame, 480p fast produces output most viewers cannot tell apart, in a fifth of the time.
What each failure actually looks like
Knowing the signature saves you from running it again a job that was never going to work.
Smeared mouth. Detail is missing rather than mistimed. The face was too small in frame. Crop or upscale the source, then try again.
Mouth slides during movement. Correct while the head is still, wrong while it moves. Stabilise or cut around the motion. Running it again unchanged reproduces it exactly.
Fault appears and disappears at fixed moments. Something crosses the mouth at those moments, usually a hand or a microphone. Not recoverable after the fact.
Right timing, wrong shapes. The mouth is synchronised to the audio but forming shapes from another language. The lip pass ran against the original track rather than the translation. This is a pipeline order problem, not a clip problem.
Drift that grows toward the end. Either the timing was not refitted after translation, or the source is variable frame rate. Phones record variable frame rate by default, so transcode to constant frame rate before you generate, which ffmpeg ↗ does in a single command.
What we do not do well
Overlapping speakers confuse the pipeline, which is why podcast style content needs a different approach, because two voices arriving at once do not separate cleanly into one mouth. Singing is a different problem and we do not solve it. For long form audio work, our podcast generator is the better starting point. Profile shots past roughly 45 degrees produce mouths that wander. If your clip has any of those, no setting fixes it and you are better off choosing a different take.
For the wider set of problems teams hit when localising video, we wrote up the five pain points of video translation.
Choosing, in one line
Start at 480p fast. Move to 720p only when the face is small in frame and the clip is short enough that spending 22 seconds of compute per second of audio is worth it to you. If you are still comparing products rather than settings, the dubbing guide for marketing teams covers the same ground from a buying angle.
You can try the pipeline on the AI video dubbing page, or see how the output compares against other platforms on our Percify vs HeyGen comparison.
Ready to Create Your Own AI Avatar?
Make a talking video of yourself from one photo, in your own voice. No watermark on any plan.
Cancel anytime from your profile
Got questions?
Frequently asked
60 credits at 480p with the fast model, 180 credits at 720p. Measured across 179 production jobs, the rate is 2.00 credits per second of audio at fast 480p and 6.00 at 720p.
About 5.7 seconds of processing per second of audio at 480p fast, so a 30-second clip finishes in roughly 3 minutes. At 720p it is 22.3 seconds per audio second, so the same clip takes about 11 minutes and a two-minute video takes about 45.
Only when the face is small in the frame. Lip-sync quality depends on how many pixels the mouth occupies, not the resolution label , a close-up at 480p has more mouth detail than a wide shot at 720p. At 3x the credits and 3.9x the wait, 720p is a fix for framing, not a general upgrade.
Translation changes segment durations and the timing was not re-fitted. German runs longer than English, Japanese shorter, so error accumulates across the clip and shows in the final seconds. Split anything longer than two minutes.